AWS Big Data Blog Official Big Data Blog of Amazon Web Services
- From silos to insights: Federated data access patterns for AI agents
 by James Wu on September 4, 2026 at 9:35 pm
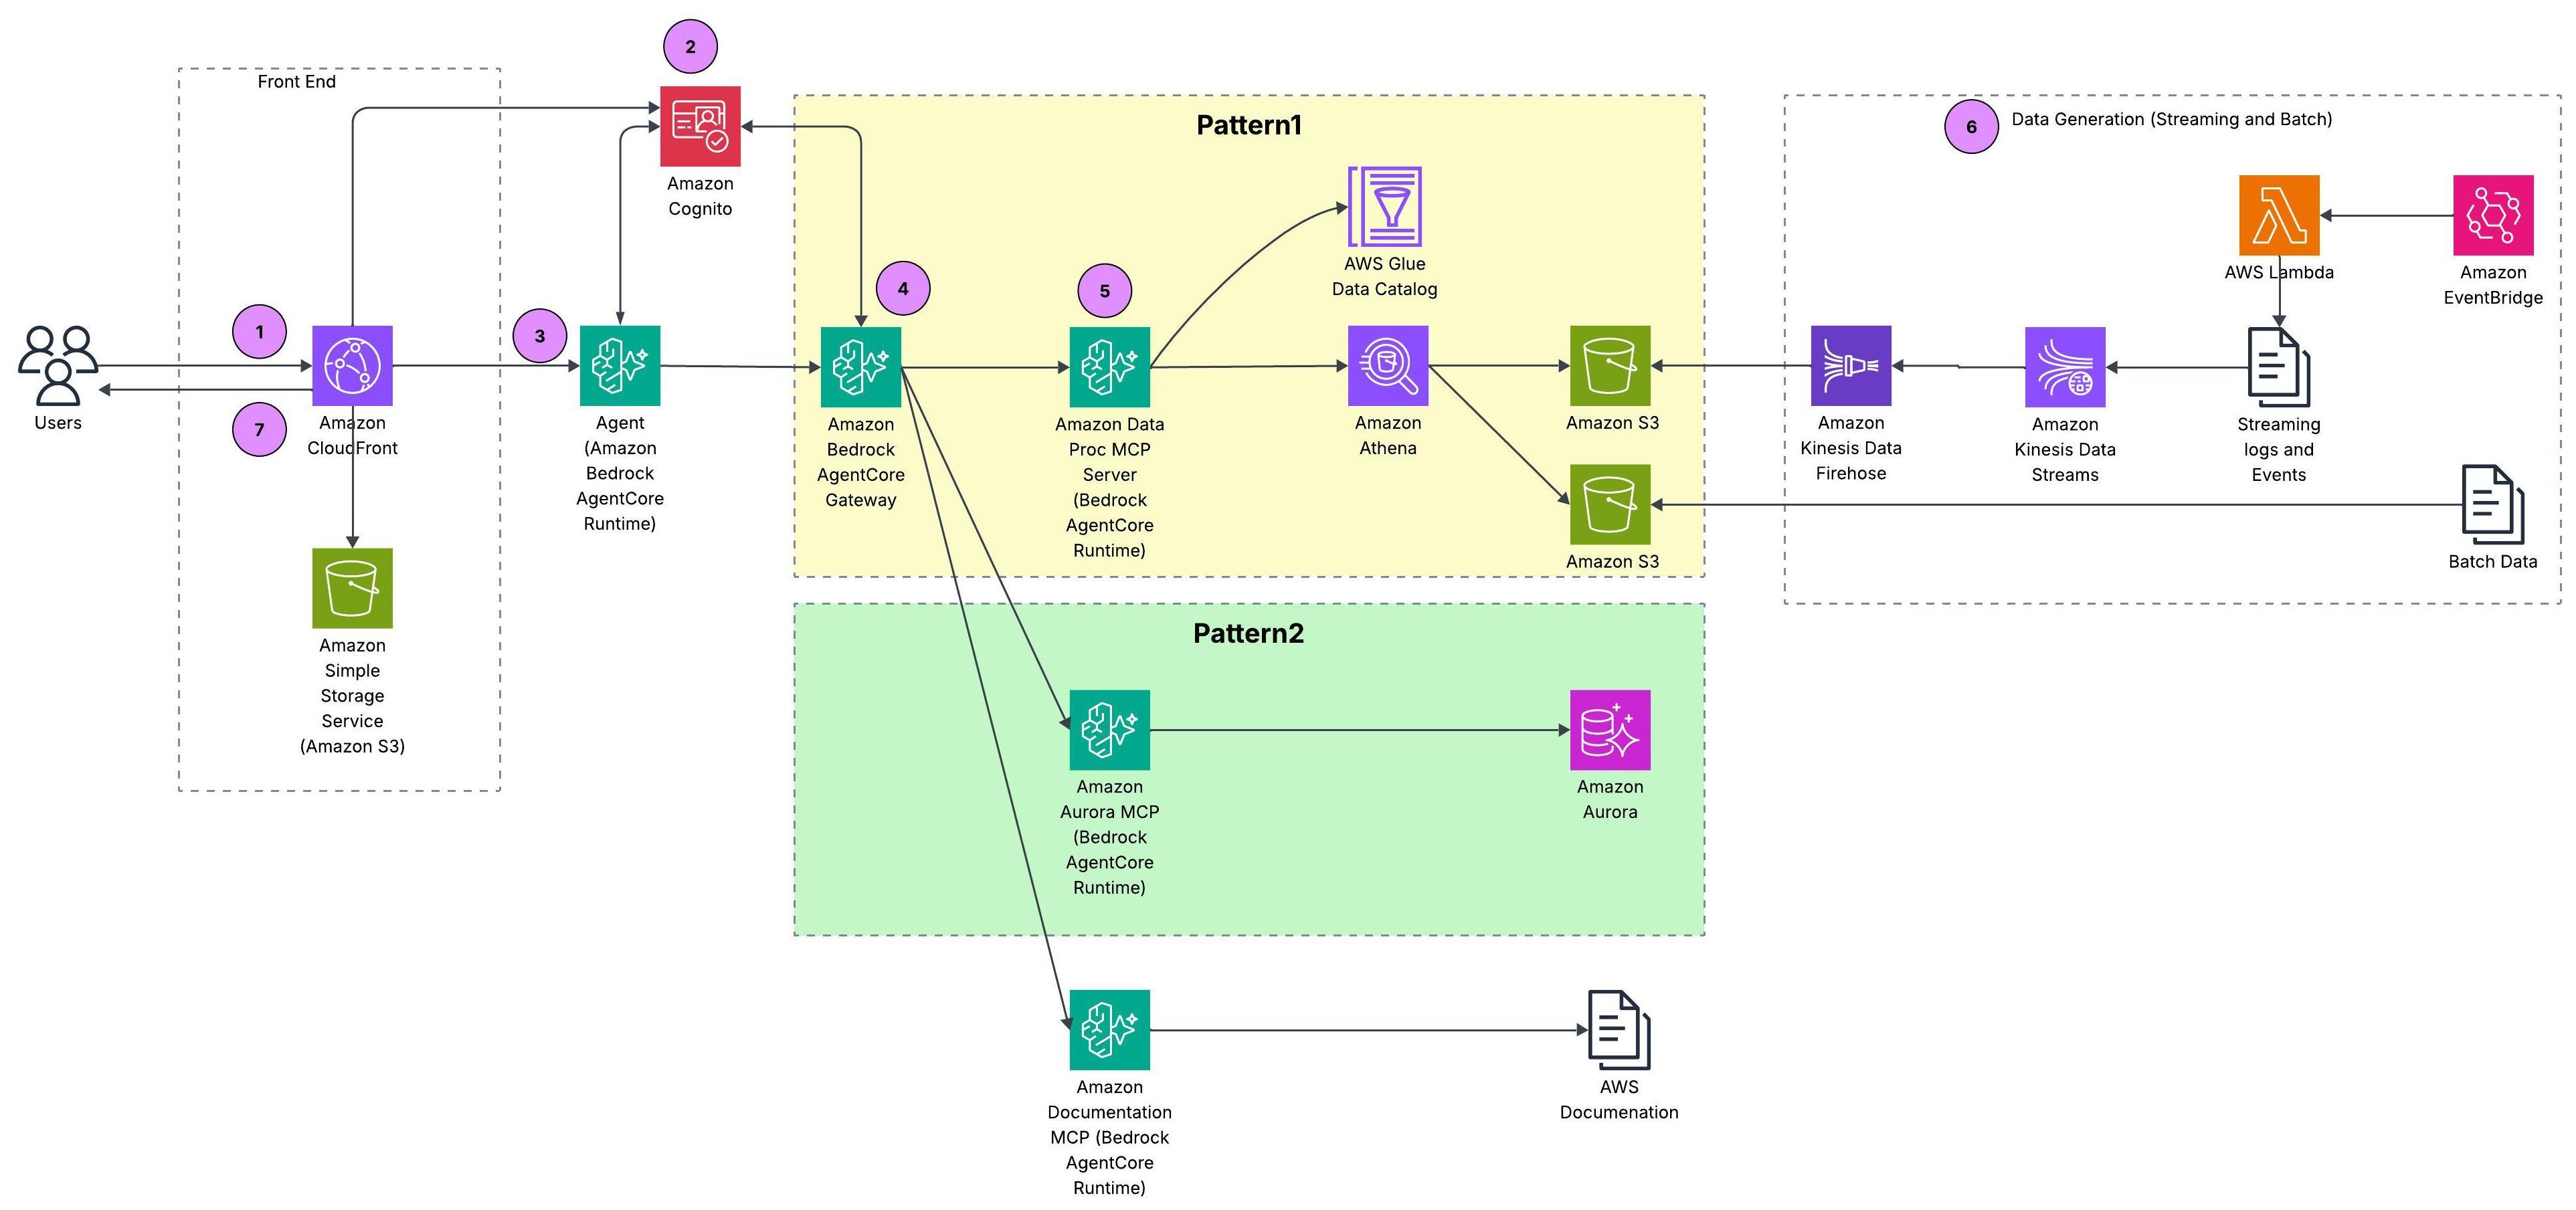
AI agents can reach enterprise data where it lives instead of routing every question through data engineers. This post presents three reference patterns for federated data access using Model Context Protocol (MCP) servers and Amazon Bedrock AgentCore: catalog-first, direct source, and hybrid access.
- Network connectivity patterns for the next generation of Amazon OpenSearch Serverless
 by Salman Ahmed on September 3, 2026 at 4:26 pm
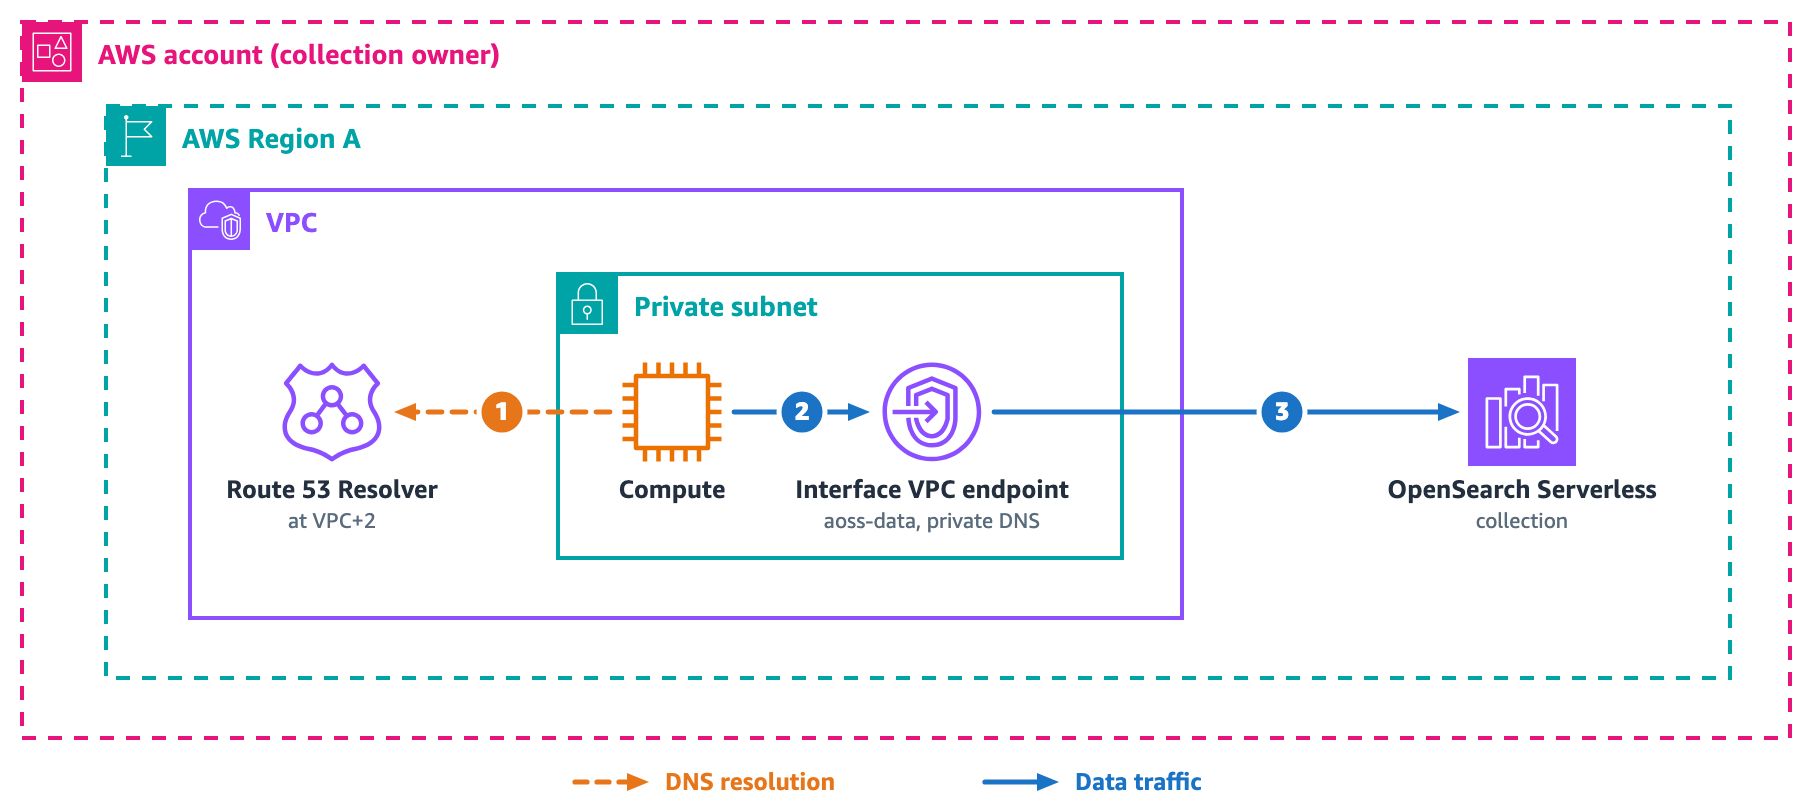
The next generation of Amazon OpenSearch Serverless uses standard AWS PrivateLink endpoints on the on.aws domain. This post shows nine connectivity patterns for private access, from a single VPC to multiple VPCs, cross-account, on-premises, and cross-Region, with the DNS resolution and data path for each.
- How Moovit achieved 33% cost optimization through architectural modernization
 by Saar Porat on September 3, 2026 at 4:23 pm
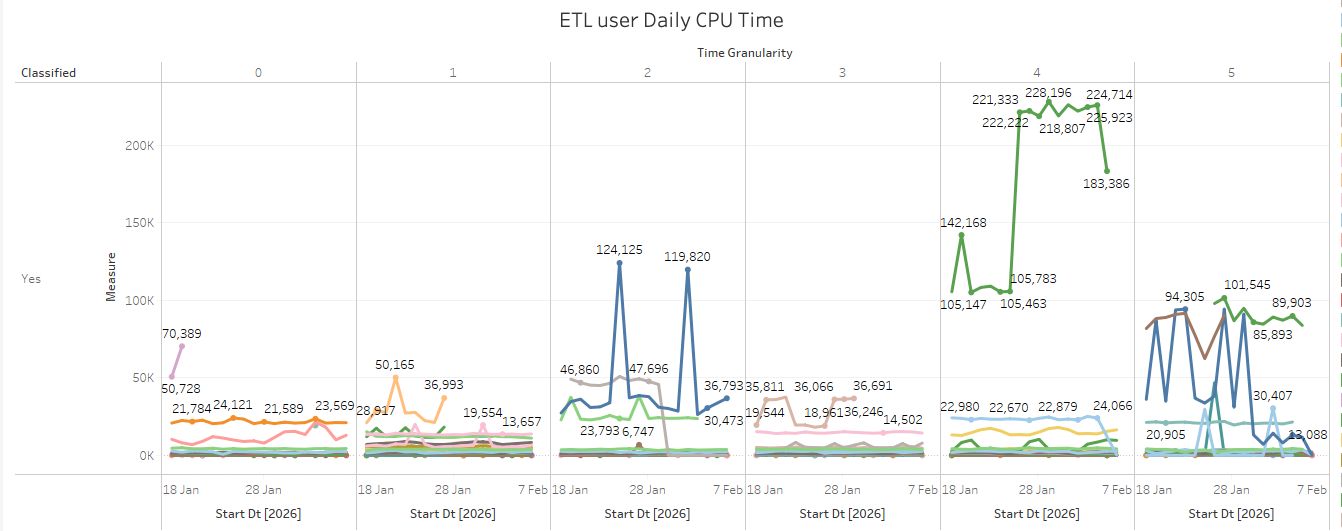
Learn how Moovit modernized its data platform with a multi-engine lakehouse architecture: offloading heavy aggregation workloads from Amazon Redshift to Amazon EMR with Spark SQL, isolating workloads with Amazon Redshift Serverless, and cutting overall data pipeline cost by 33%.
- Query Amazon S3 Tables from Amazon EMR Trino using the Iceberg REST endpoint
 by Shubham Purwar on September 2, 2026 at 7:01 pm
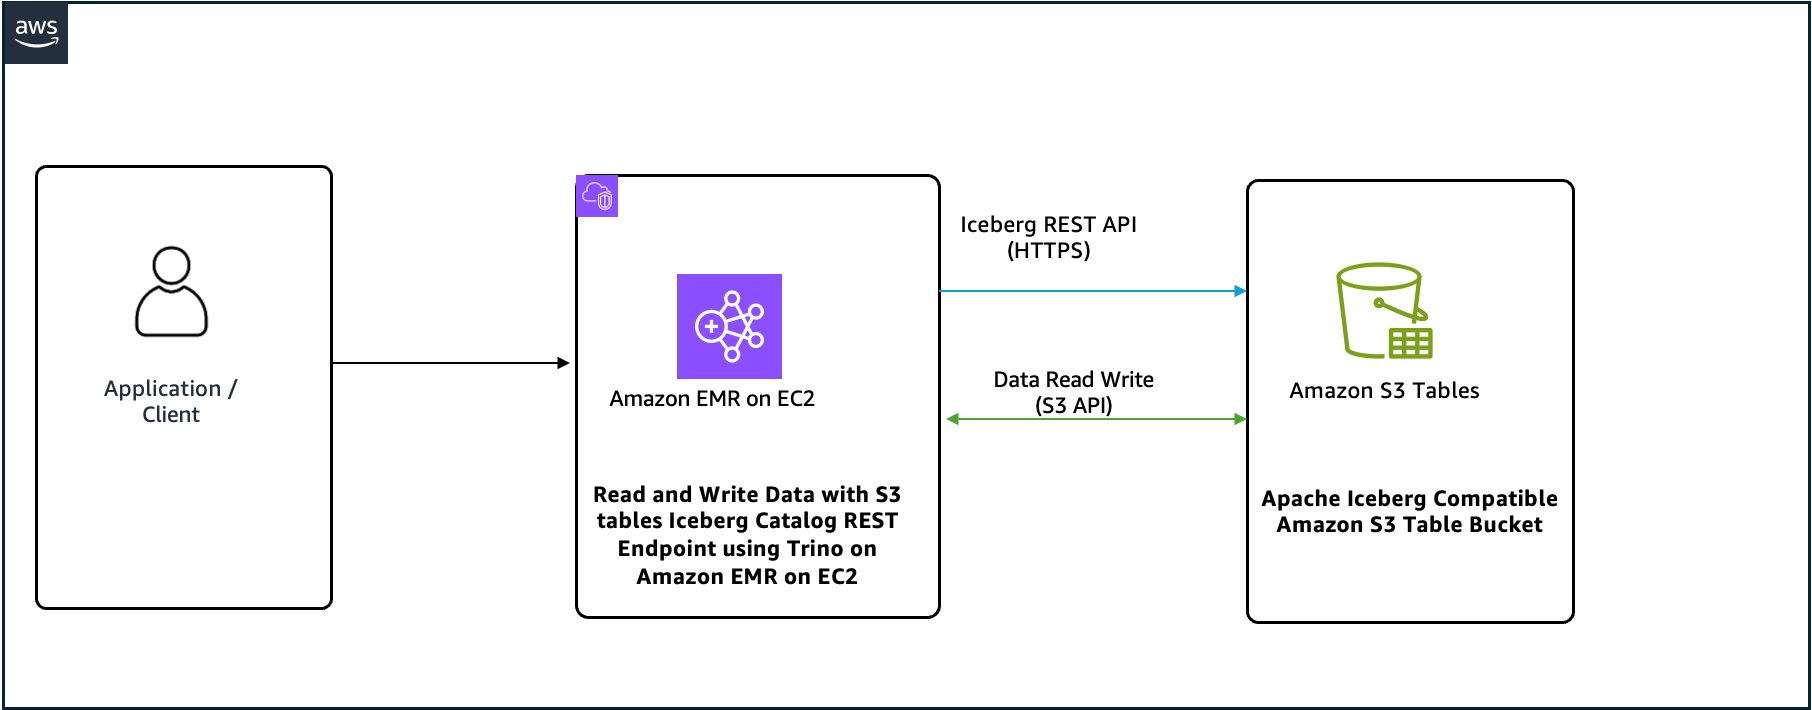
Learn how to query Amazon S3 Tables from Trino on Amazon EMR using the Apache Iceberg REST catalog endpoint. This post shows how to deploy the integration with AWS CloudFormation, configure the Trino catalog, and run SQL to create, query, and manage Apache Iceberg tables.
- Building medallion architecture with Iceberg materialized views in Amazon SageMaker
 by Gaurav Sharma on September 2, 2026 at 6:34 pm
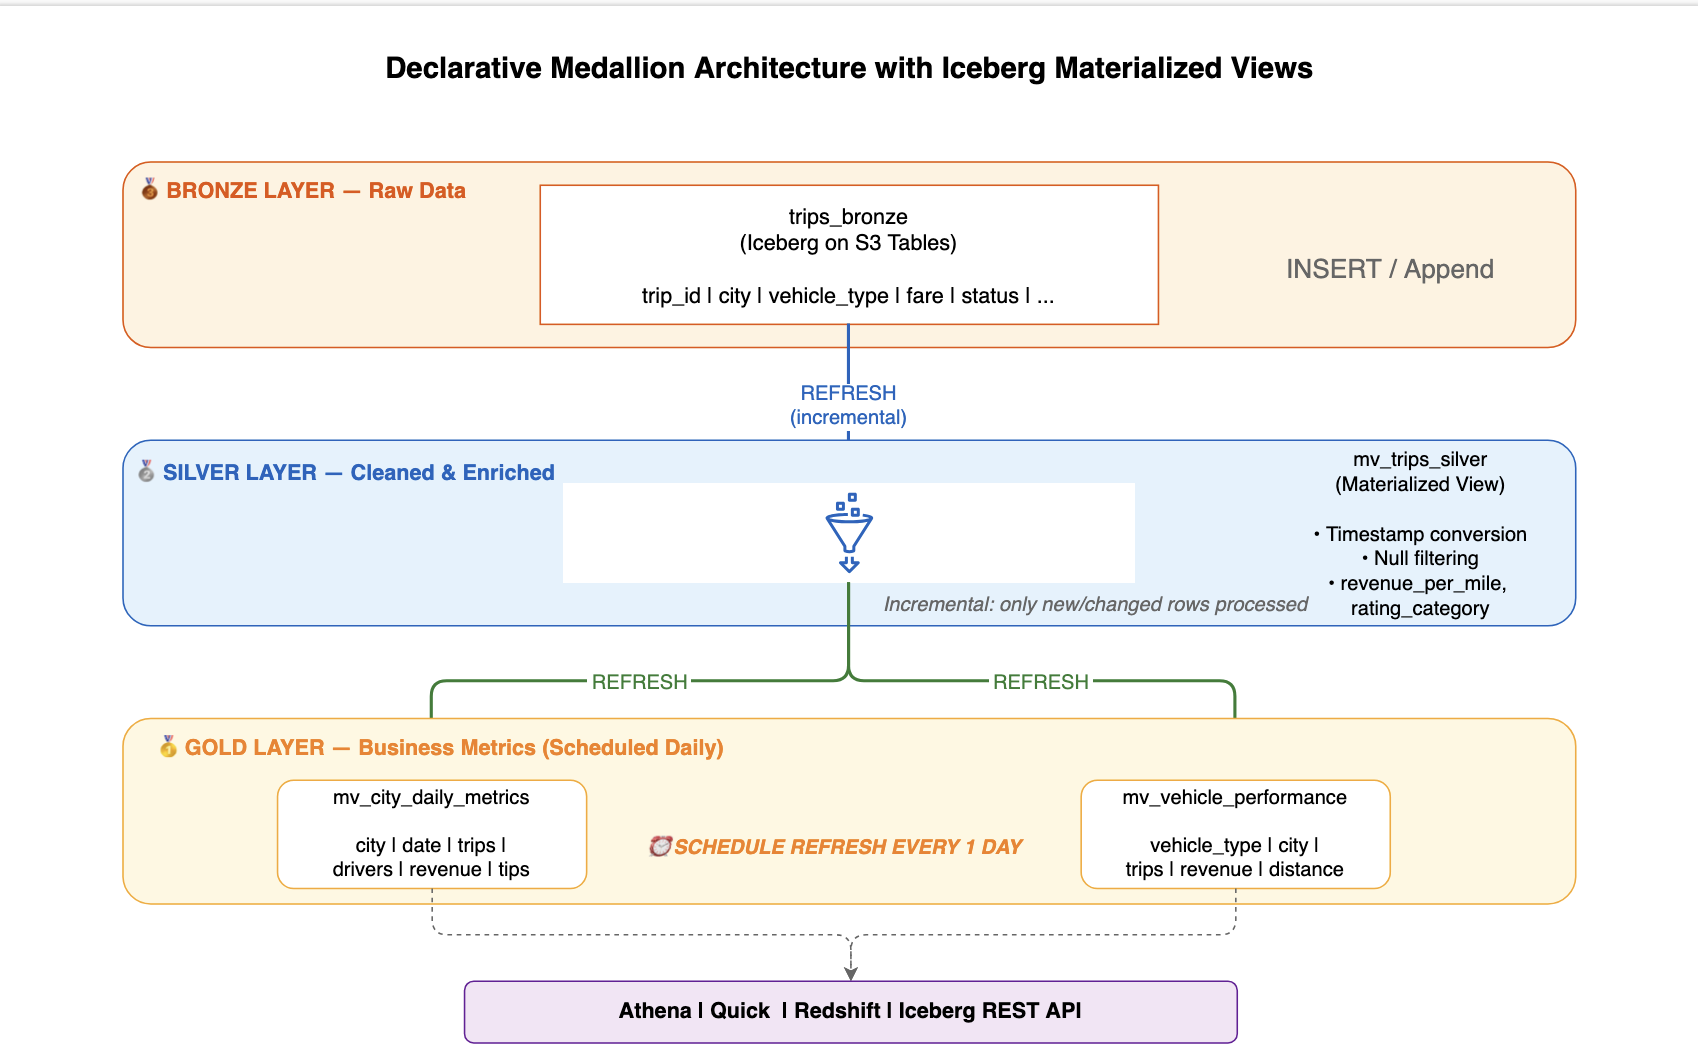
With Apache Iceberg materialized views in Amazon SageMaker, you can build a Bronze, Silver, and Gold medallion architecture as three SQL statements. This declarative approach folds transformation, orchestration, and incremental processing into per-layer definitions, with no ETL jobs, orchestrators, or change-data-capture code to maintain.
- Build a dynamic streaming data lake with Apache Iceberg and Apache Flink
 by Francisco Morillo on September 2, 2026 at 6:28 pm
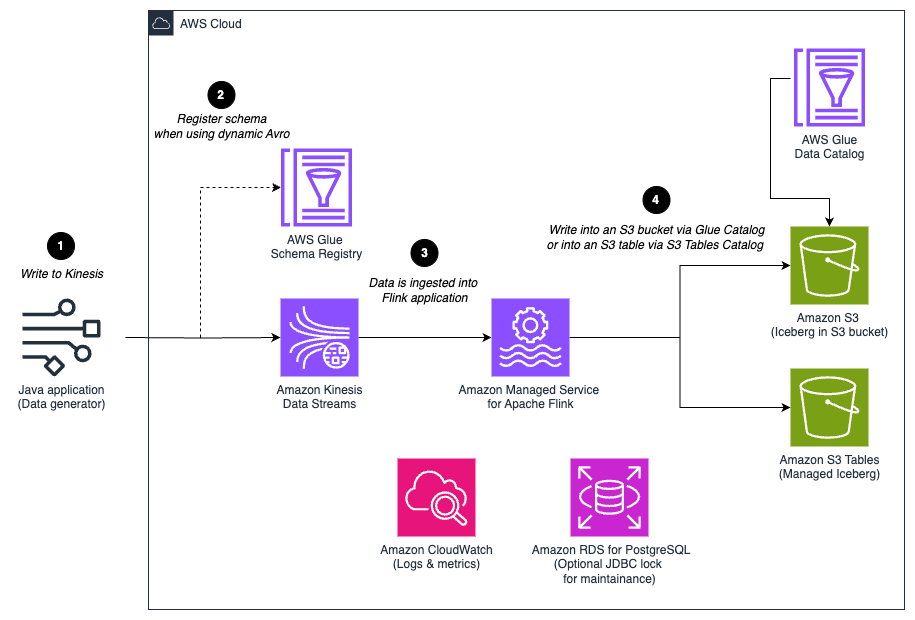
Learn how to build a dynamic streaming data lake on Amazon Managed Service for Apache Flink that adapts to new event types and schema changes without stopping the pipeline, using Apache Iceberg’s Dynamic Iceberg Sink for per-record table routing and automatic schema evolution.
- Observing and evaluating production agents using OpenSearch Agent Health
 by Ulrich Hinze on September 1, 2026 at 4:19 pm
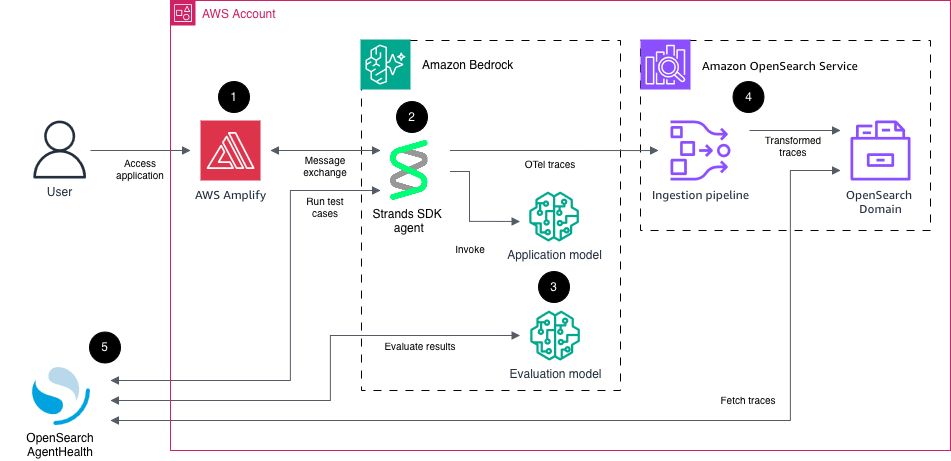
Learn how to observe and evaluate production AI agents by combining an agent running on AWS with OpenSearch Agent Health. This post walks through deploying an agent and its observability pipeline to AWS, then using Agent Health to explore traces and run evaluations that measure and improve agent quality over time.
- Accelerate Apache Spark debugging on Amazon EMR with AWS DevOps Agent
 by Kalyan Janaki on September 1, 2026 at 4:06 pm
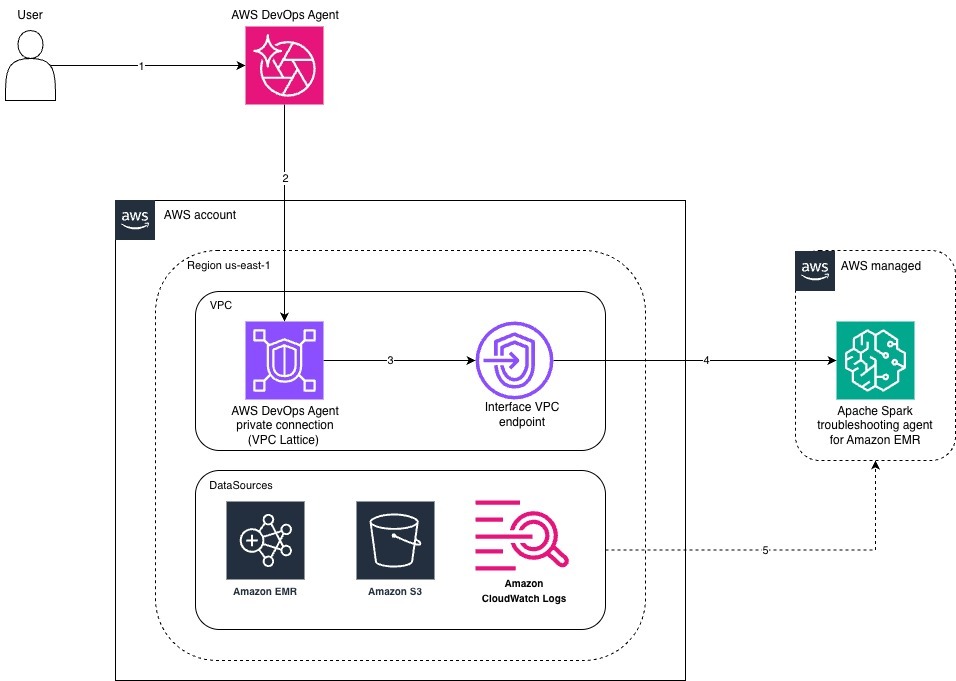
Extend AWS DevOps Agent to investigate Apache Spark failures on Amazon EMR. This post shows how to register the Apache Spark Troubleshooting Agent for Amazon EMR as a custom MCP capability provider over AWS PrivateLink, so a single agent chat session diagnoses a failing Spark job from an Amazon CloudWatch alarm to a line-numbered root cause.
- Deliver real-time data to streaming tables for Apache Iceberg with Amazon Kinesis Data Streams
 by Nikit Pednekar on August 31, 2026 at 11:03 pm
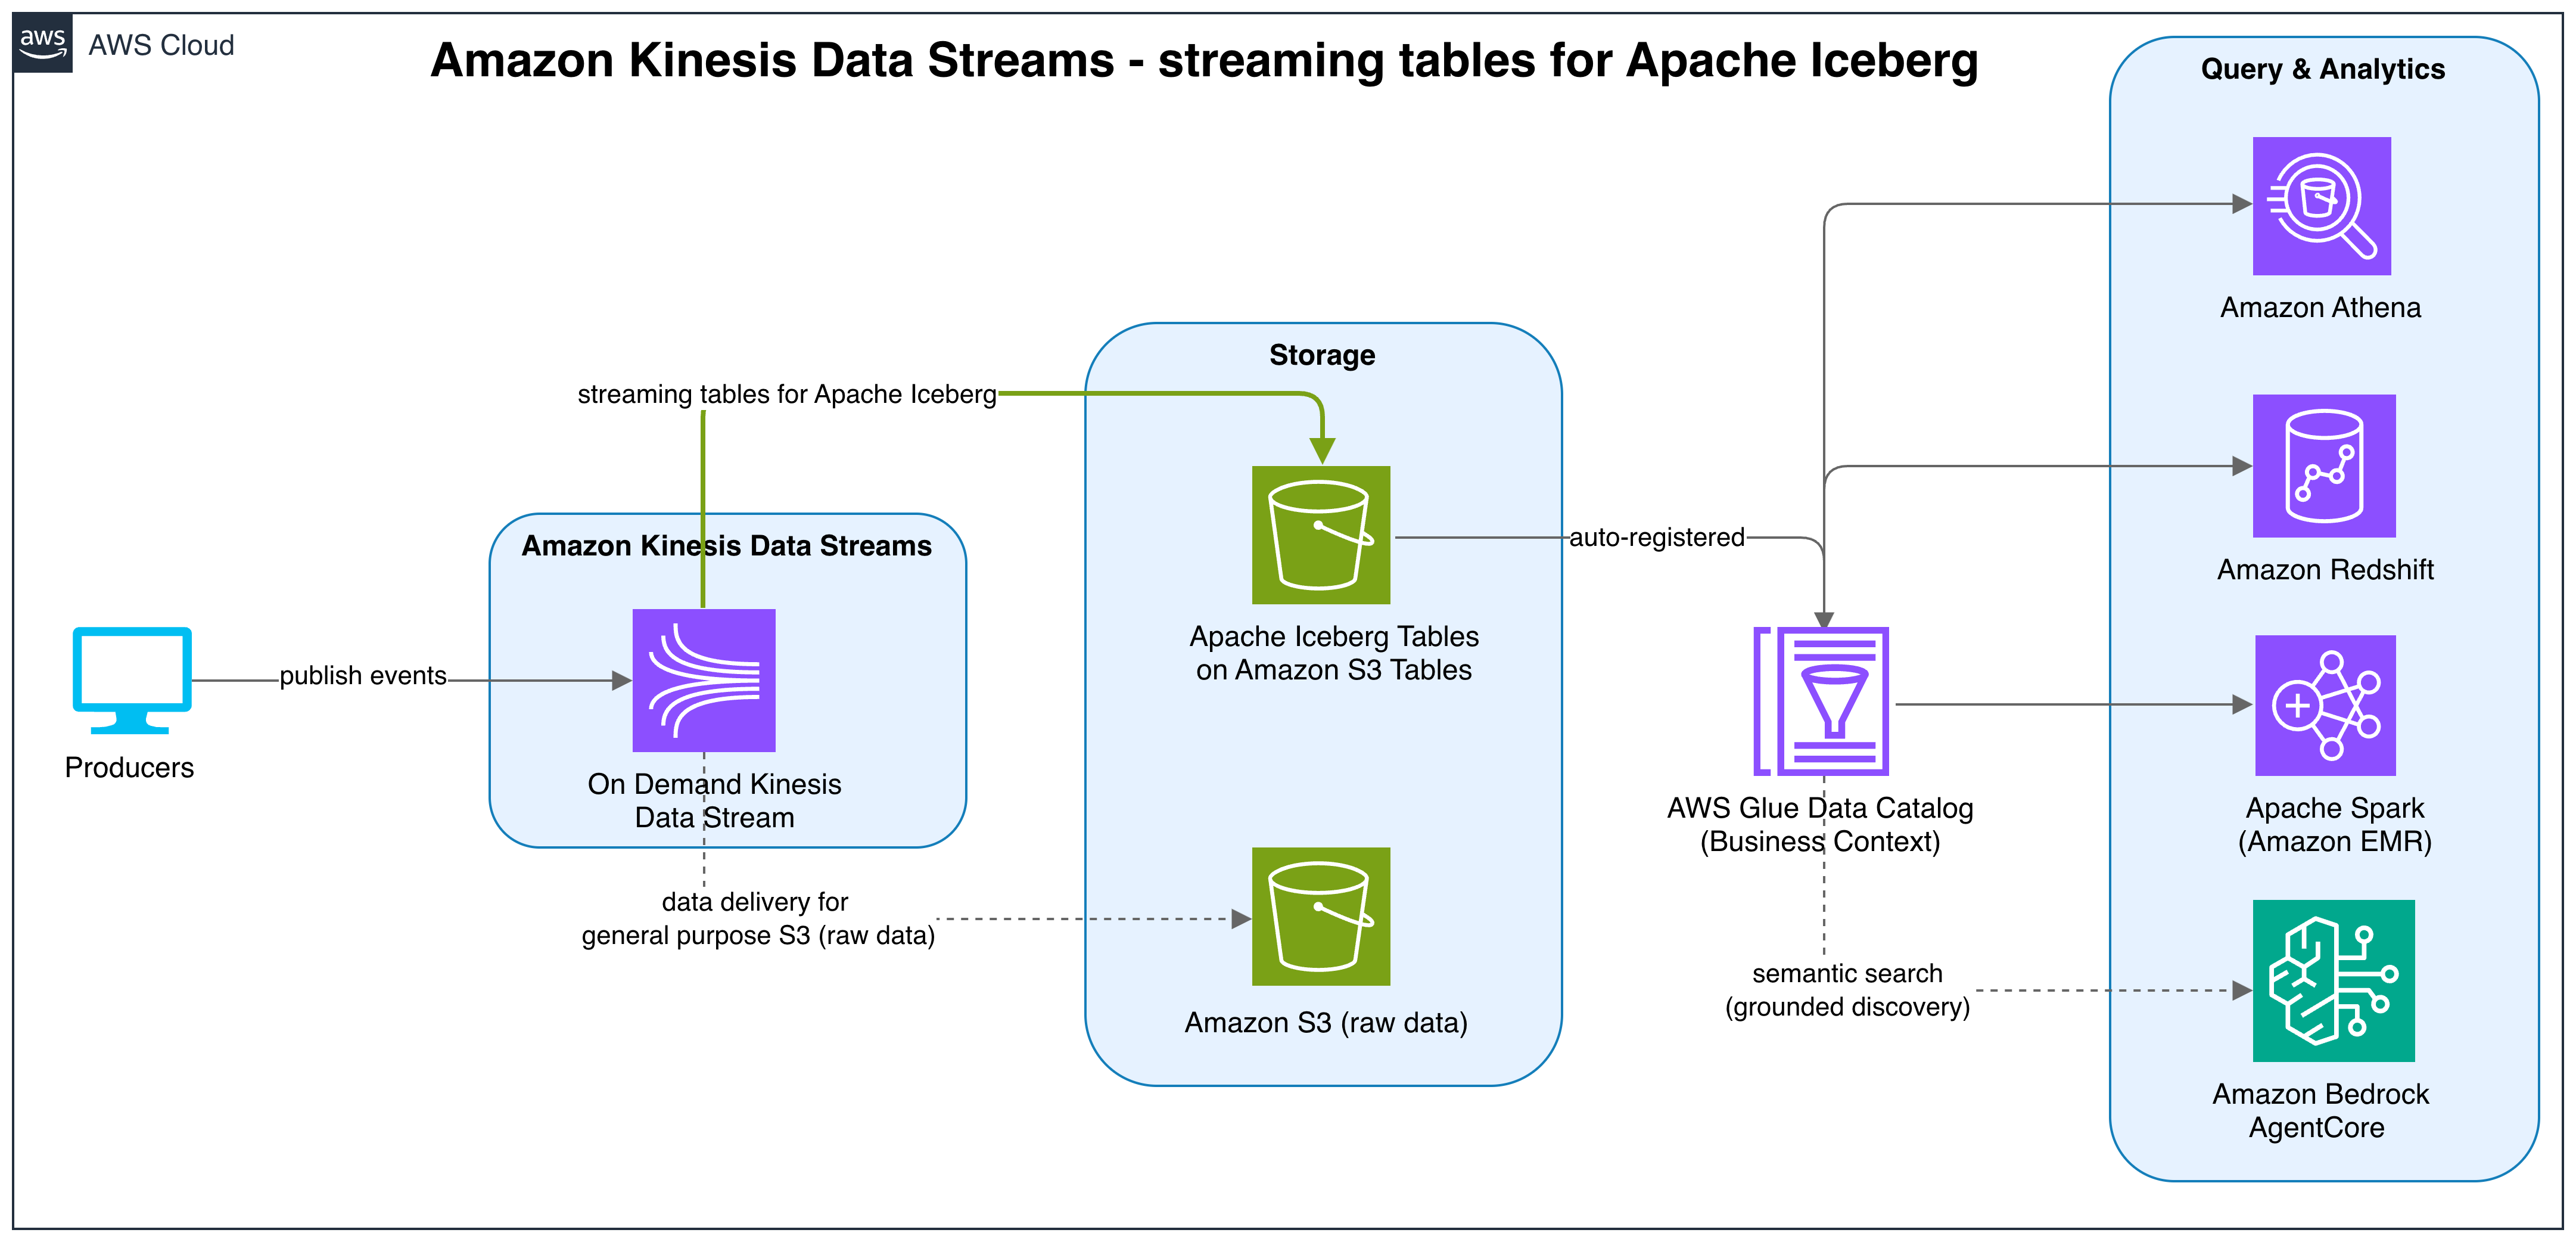
Amazon Kinesis Data Streams now supports streaming tables, a fully managed capability that continuously delivers your streaming data as queryable Apache Iceberg tables on Amazon S3 Tables. Streaming tables reduce data delivery costs to S3 Tables by up to 50% compared to self-managed alternatives and reduce downstream query costs by up to 30% through intelligent inline compaction that eliminates the small file problem. You need no custom applications, no self-managed compute, and no operational overhead.
- Measuring and improving search quality with Amazon OpenSearch Service
 by Aruna Govindaraju on August 31, 2026 at 9:13 pm
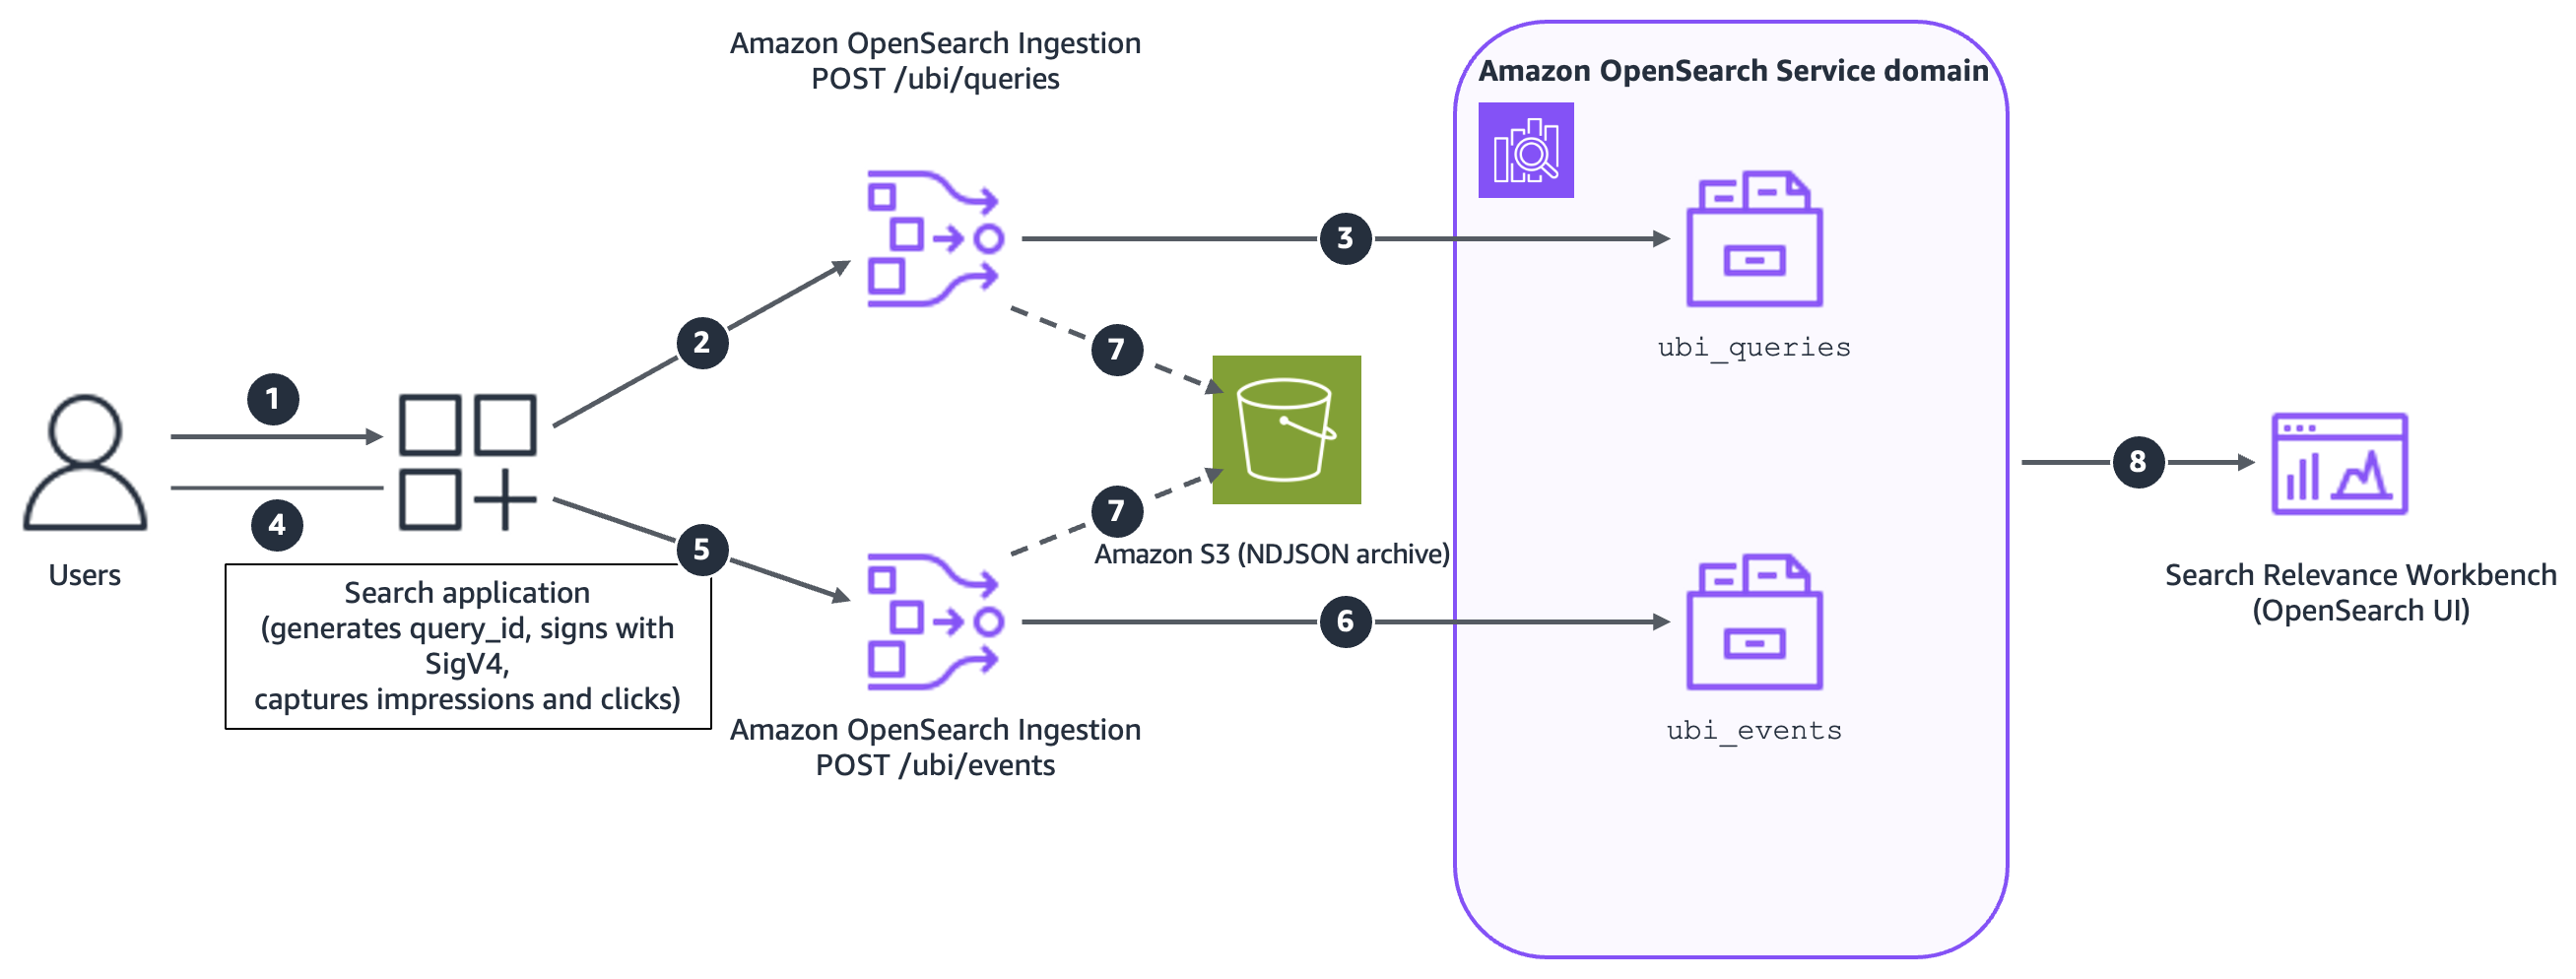
Most teams struggle to answer a deceptively simple question: is my search returning relevant results? This post shows how to capture User Behavior Insights (UBI) data on Amazon OpenSearch Service and use Search Relevance Workbench (SRW) to turn those signals into relevance judgments and evaluate search quality.
- Integrate Amazon Redshift and IAM Identity Center with enhanced VPC routing
 by Maneesh Sharma on August 31, 2026 at 5:22 pm
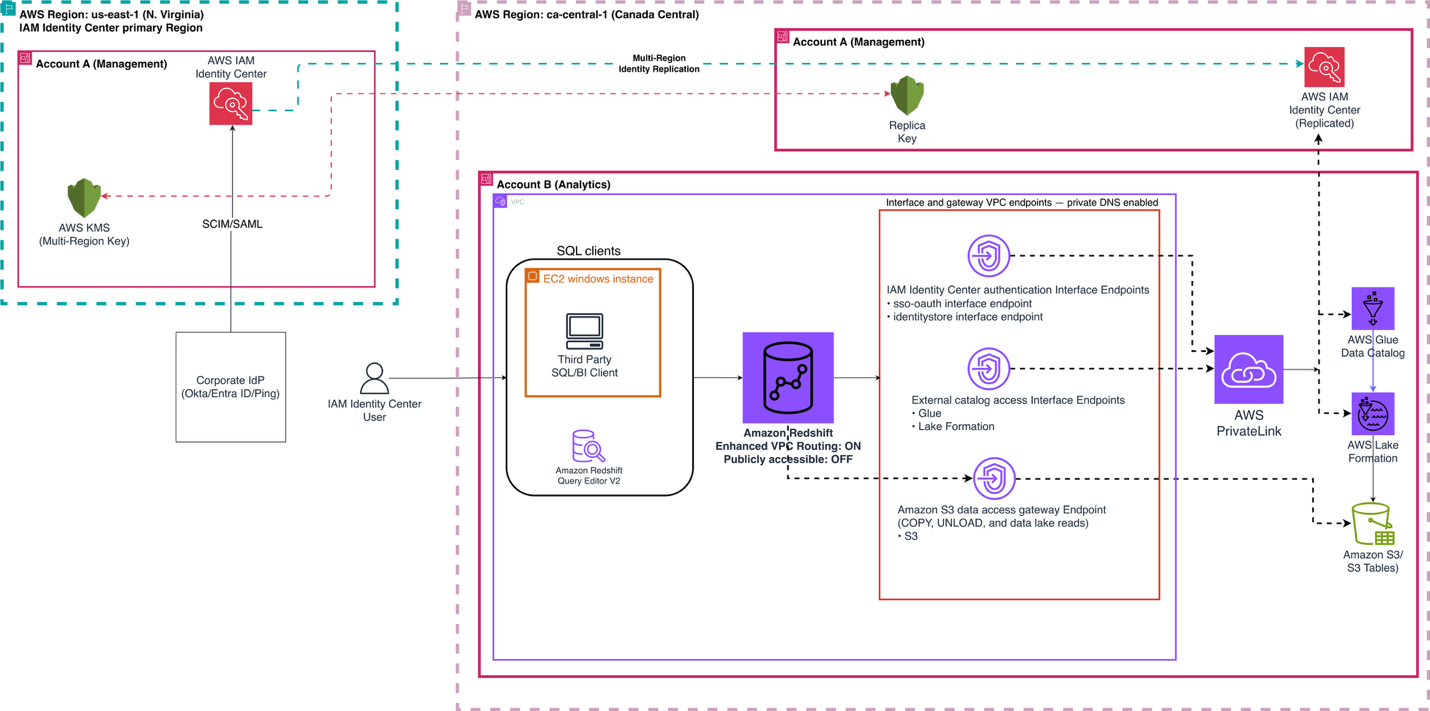
Amazon Redshift now supports AWS IAM Identity Center authentication on clusters and workgroups that use enhanced VPC routing. Create two interface VPC endpoints to give your users single sign-on with their corporate credentials while keeping all authentication traffic on the AWS private network.
- Build a real-time event pipeline with Spark Real-Time Mode on AWS Glue 6.0
 by Shoukat Ghouse on August 31, 2026 at 4:22 pm
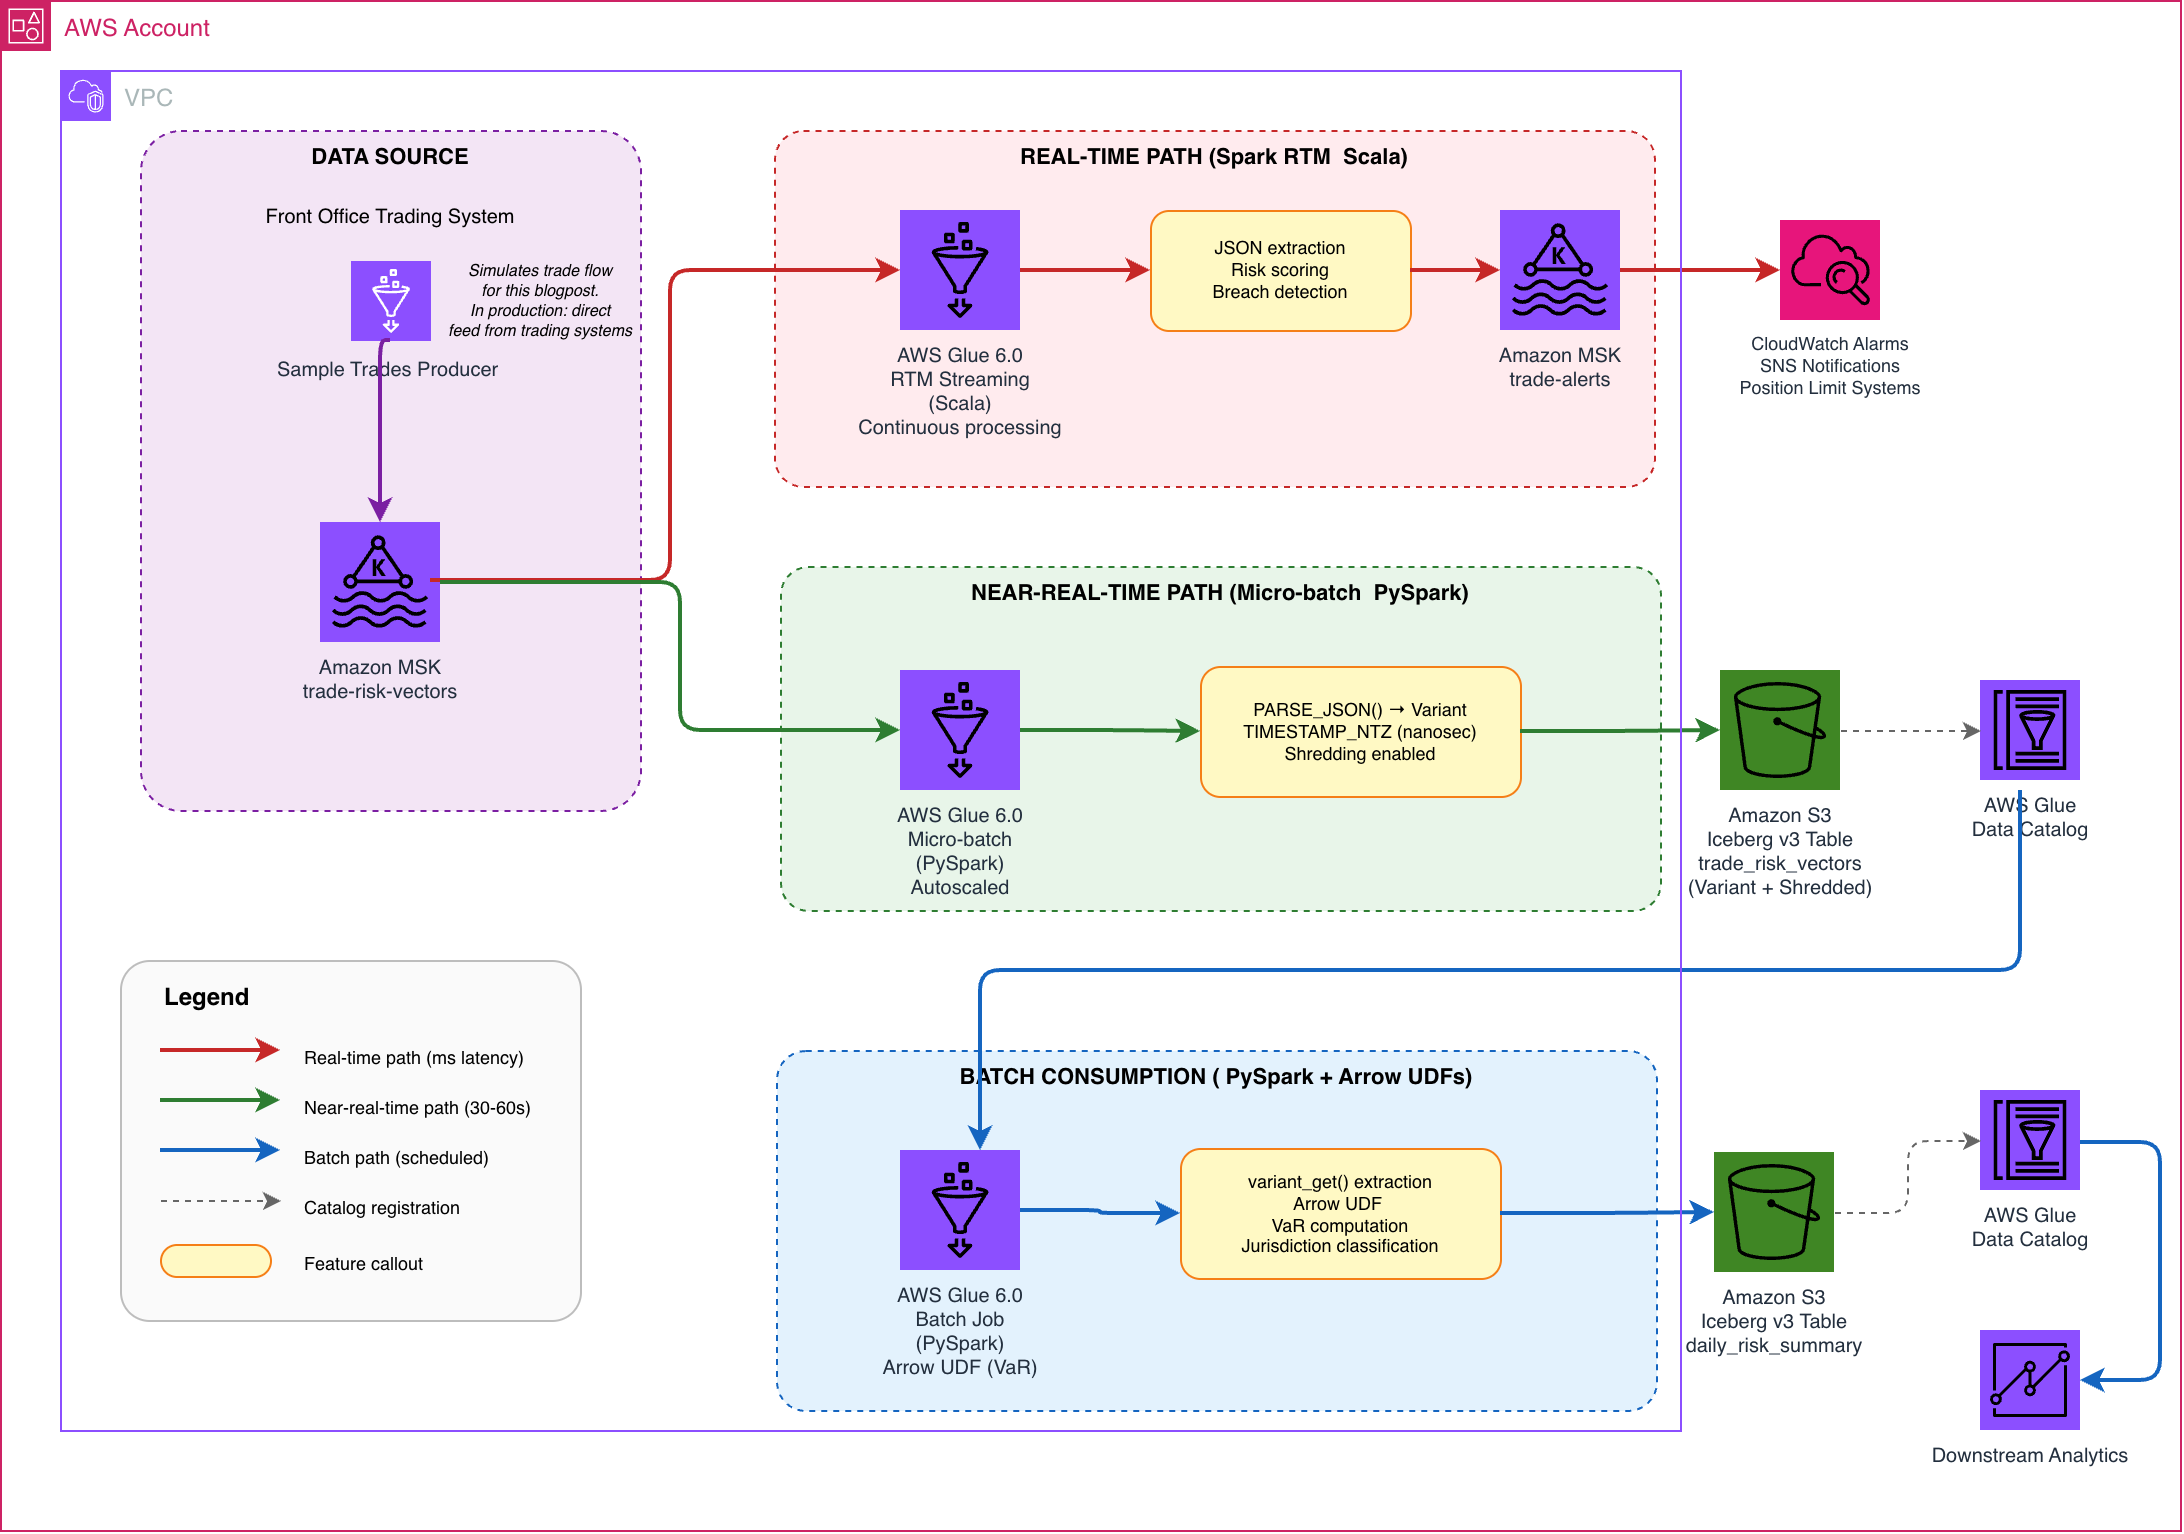
With AWS Glue 6.0, you can build real-time, near-real-time, and batch data pipelines on a single platform. Using a financial market-risk example, learn how to flag high-risk trades with sub-second latency using Spark Real-Time Mode, store heterogeneous pricing vectors with Apache Iceberg v3 Variant columns, and run batch analytics with Arrow-native UDFs.
- Razor Group’s journey to a modern data lakehouse on AWS
 by Yaswanth Kothainti on August 28, 2026 at 4:25 pm
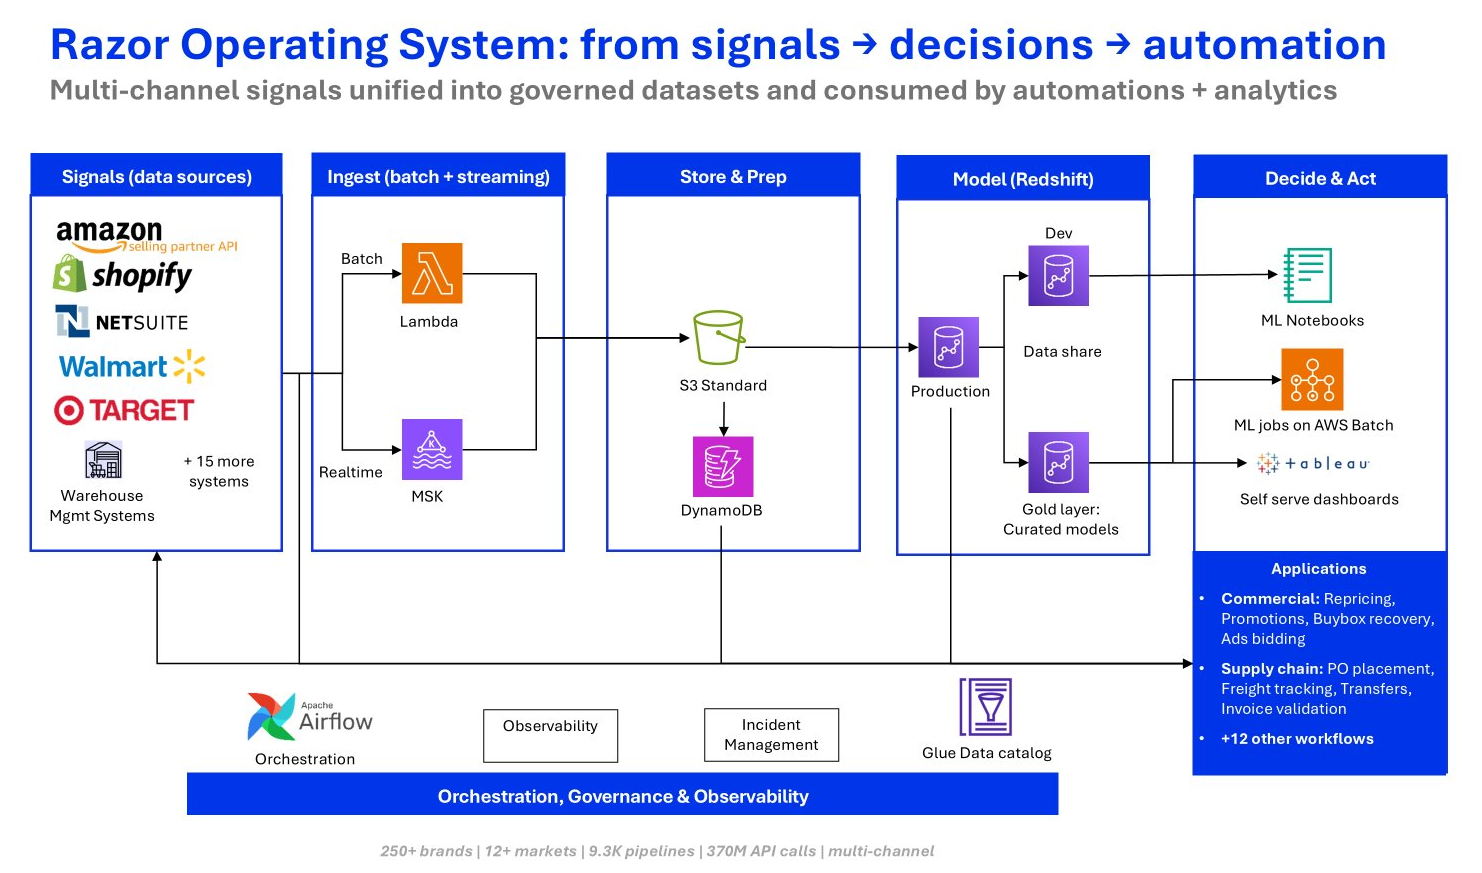
Razor Group, one of Europe’s leading ecommerce aggregators managing 250+ brands, migrated from always-on Amazon Redshift clusters to an open lakehouse on Apache Iceberg, Amazon S3 Tables, and Apache Spark. Learn the architectural decisions, the five-phase migration, and the results: 65% faster P95 queries and a 63% infrastructure cost reduction.
- How Picnic configured multiple OAuth providers for Amazon MQ
 by Oscar Mapfumo Sibanda on August 27, 2026 at 4:07 pm
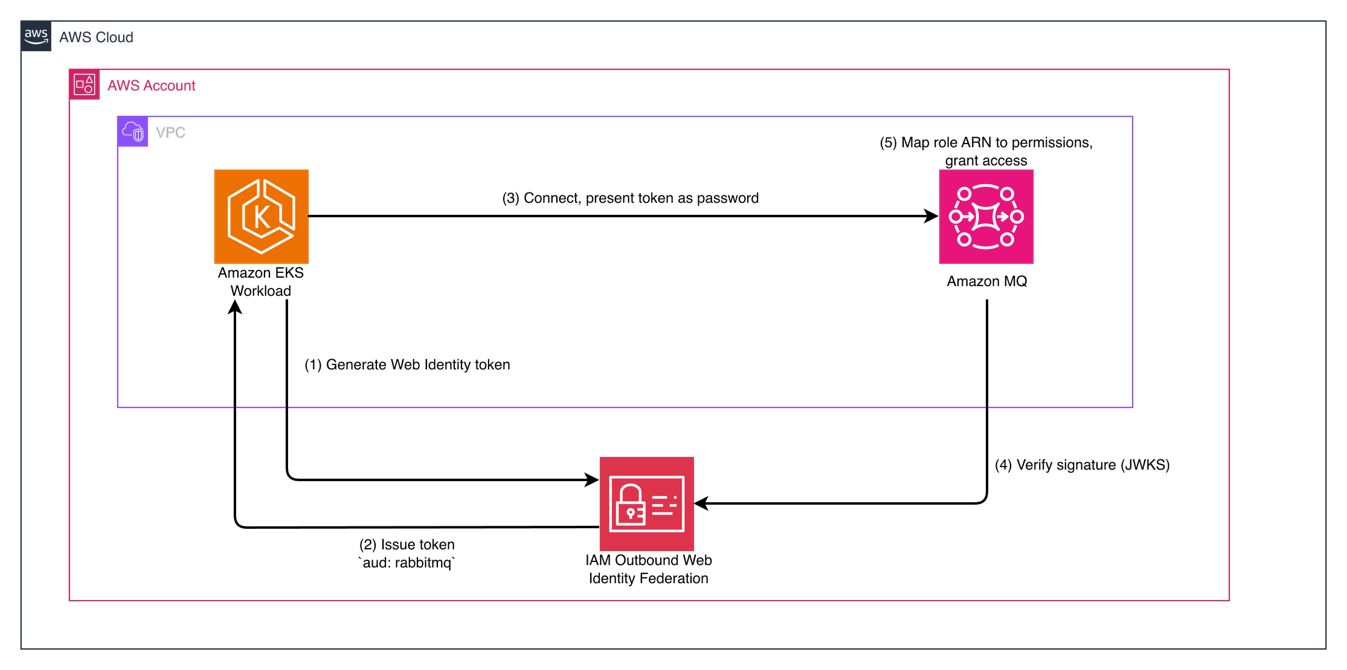
Picnic runs RabbitMQ as the messaging backbone for hundreds of microservices on Amazon MQ for RabbitMQ. This post shows how to configure one broker to trust multiple OAuth 2.0 identity providers, Keycloak for operators and AWS IAM for services, so you can eliminate static credentials while maintaining separate identity paths for people and workloads.
- Build with geospatial and variant types in Iceberg v3 on AWS Glue 6.0
 by Shoukat Ghouse on August 27, 2026 at 4:00 pm
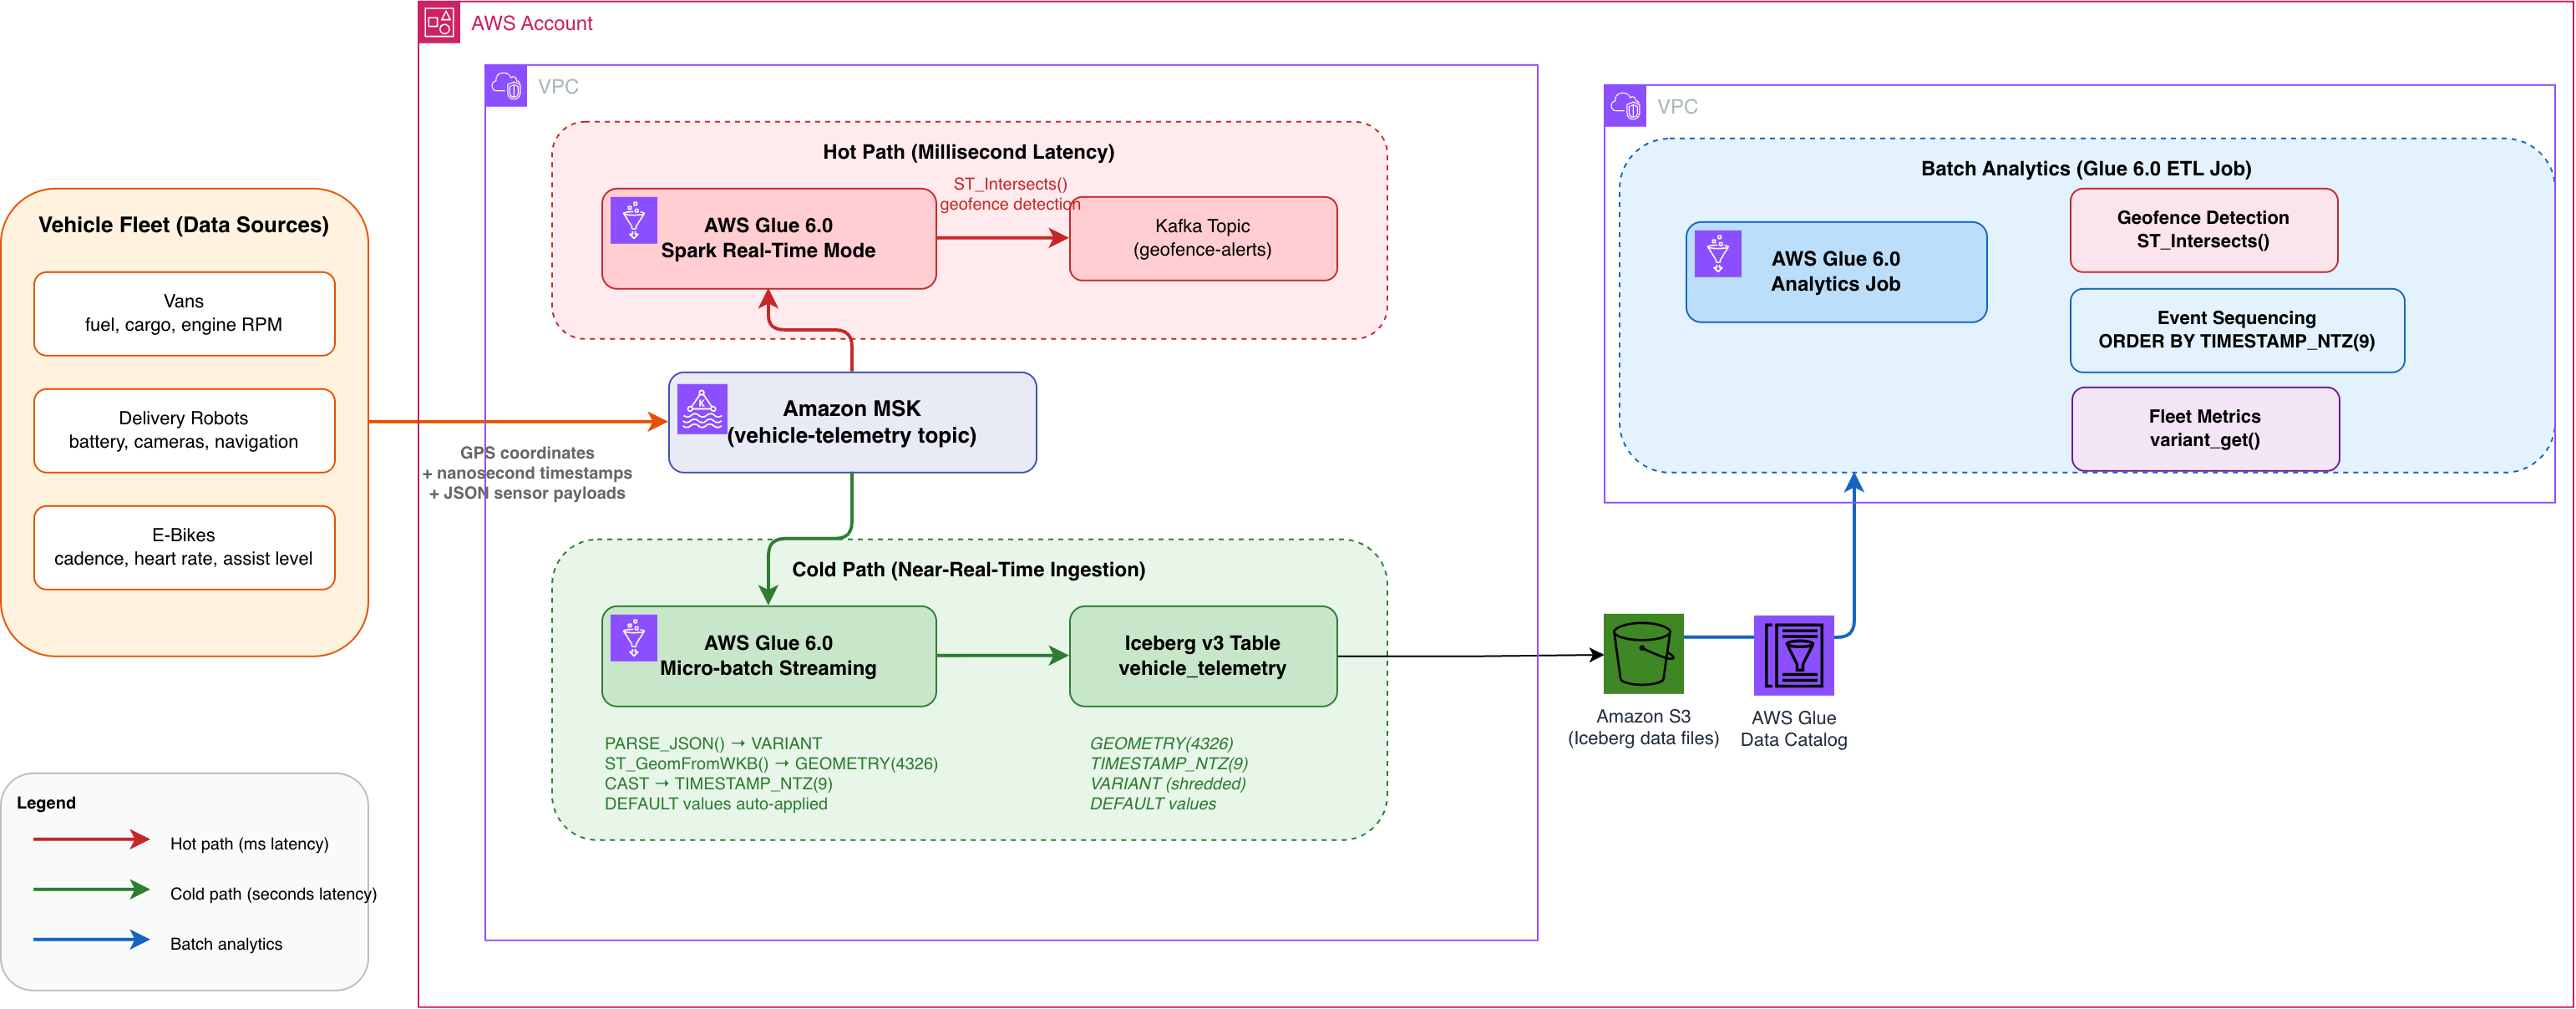
AWS Glue 6.0 with Apache Spark 4.1 adds support for Apache Iceberg v3: native geospatial types, nanosecond-precision timestamps, the VARIANT type, and DEFAULT column values. This post builds a connected vehicle fleet telemetry pipeline that uses all four in a single Iceberg v3 table, from ingestion through spatial, nanosecond, and variant queries.
- Migrate an OAuth 2.0 authenticated Apache Kafka cluster to Amazon MSK with MSK Replicator
 by Subham Rakshit on August 26, 2026 at 7:11 pm
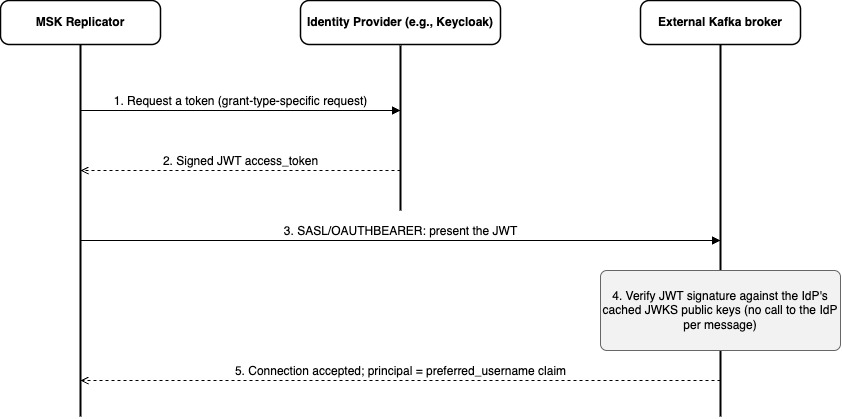
MSK Replicator now supports OAuth 2.0 (SASL/OAUTHBEARER) authentication to external Apache Kafka clusters. This post walks through the three supported grant types, how to configure Replicator for each, the network and TLS prerequisites that are commonly missed, and how to handle identity providers behind an additional federation layer.
- Announcing in-place ZooKeeper-to-KRaft cluster upgrades for Amazon MSK
 by Austin Groeneveld on August 26, 2026 at 6:59 pm
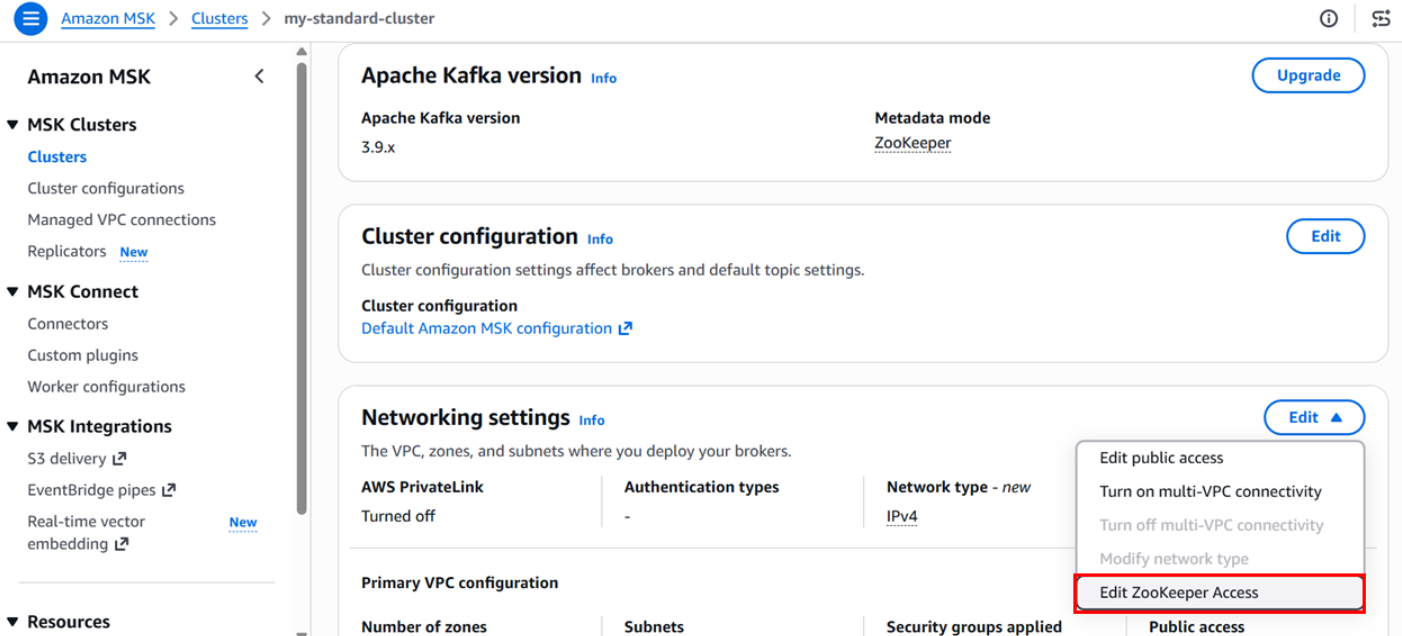
Amazon MSK now supports in-place upgrades from ZooKeeper to KRaft metadata mode. You can modernize your existing cluster’s metadata management through the familiar version upgrade workflow, with no new cluster to provision and no data migration. This post covers the prerequisites and the step-by-step upgrade process.
- Amazon MSK Service 101: How many partitions does an Amazon MSK topic need?
 by Yashika Jain on August 26, 2026 at 3:56 pm
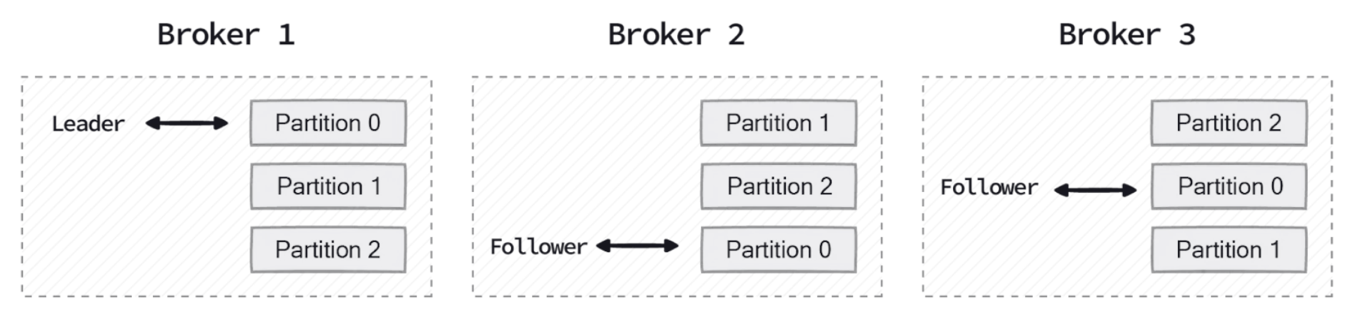
How many partitions does your Amazon MSK topic need? Choosing the right partition count affects throughput, scalability, and operational complexity. This post provides practical guidance for sizing partitions, covering per-partition throughput, consumer parallelism, partition keys, and Amazon MSK partition-per-broker guidelines.
- AWS and DuckLabs: Building the future of analytics together
 by Mai-Lan Tomsen Bukovec on August 26, 2026 at 1:28 pm
Today we are announcing that Amazon has signed a definitive agreement to acquire DuckLabs, the Amsterdam-based company behind the open-source analytical database DuckDB. We expect the transaction to close shortly, subject to customary closing conditions. Hannes Mühleisen and Mark Raasveldt, who created DuckDB and co-founded DuckLabs, will continue leading the team and the open-source project’s technical direction as part of AWS. The DuckDB open-source project will also continue to be driven by the DuckLabs team, remain open source under the independent Foundation (the non-profit that oversees DuckDB), and available under the MIT license as it does today.
- PythonOperator and BashOperator Now Available on Amazon Managed Workflows for Apache Airflow (Amazon MWAA) Serverless
 by Pradeep Kumar Nalluri on August 25, 2026 at 7:28 pm
You can now use PythonOperator and BashOperator to run custom Python functions and shell scripts directly in the Amazon MWAA Serverless runtime, without provisioning additional infrastructure. This post walks through building a serverless pipeline that converts CSV files to JSON using a PythonOperator and verifies the output with a BashOperator.